
Table of Contents
- Introduction
- Setup
- Match Names That Look Alike with RapidFuzz
- Match Meaning with Sentence Transformers
- Ask Jev Which Product Is the Same
- Combine Sentence Transformers and Jev
- Which Approach Should You Use?
Introduction
In a previous article, I compared four text similarity tools, from regex to Sentence Transformers. Fuzzy matching handled typos and word order, and embeddings handled different words with the same meaning:
Jon Smith    John Smith       <- typo, fuzzy matching catches it
NYC          New York City    <- abbreviation, embeddings catch it
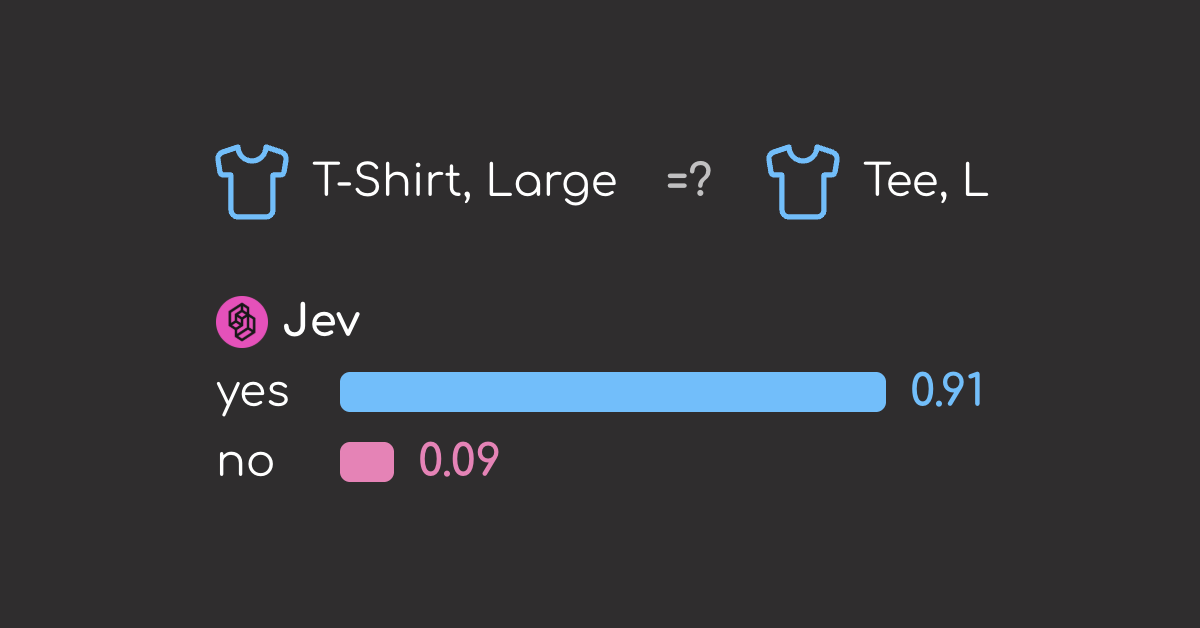
One case none of them handled well is two records that describe the same product in different words:
Haier 13' Silver Tube TV - HTR13
13in Crt Tv W/atsc Tuner - HTR13     <- same model (HTR13), different words
An LLM could decide what makes two products the same, for example with PydanticAI forcing a yes or no answer, but running one on every product would be slow and expensive. TypeSafe Jev is a cheaper option: it picks from fixed answers instead of writing a reply, and you can still give it your own rules.
This article tests whether Jev can catch the mistakes RapidFuzz and Sentence Transformers make, and what it costs to run.
💻 Get the Code: The full script and setup are in the GitHub companion folder.
Stay Current with CodeCut
Easy-to-digest articles on Python, AI, and open-source tools. Delivered twice a week.
Setup
Install the libraries:
pip install rapidfuzz sentence-transformers typesafe-sdk pandas python-dotenv
This article uses rapidfuzz v3.14.6, sentence-transformers v5.6.0, typesafe-sdk v0.7.5, and pandas v2.3.3.
The Abt-Buy benchmark has two product lists, 1,081 products from Abt (the first list) and 1,092 from Buy.com (the second list), plus a file of the 1,097 known matches. I use it to count each tool’s correct and wrong merges.
first list (1,081)          second list (1,092)
Samsung ... SBH500  ──────  Samsung SBH500 ...
Sony ... CDPCX455   ──────  Sony CDP-CX455 ...
...                         Sony CDP-CX355 ...
                            ...
The code below shows only the call that matters for each tool. The data download and the full code are in the companion folder.
Match Names That Look Alike with RapidFuzz
RapidFuzz is a fast fuzzy string matching library. It scores how similar two strings look from 0 to 100.
John Smith   vs   Smith, John      100   same words
John Smith   vs   Jon Smith         95   one letter off
John Smith   vs   Mary Jones        50   different names
Let’s start with an easy case for RapidFuzz: the same product, with the same words in a different order.
First list:    Samsung Stereo Bluetooth Headset In Black - SBH500
Right match:   Samsung SBH500 Stereo Bluetooth Headset
Ask RapidFuzz for the closest match in the second list:
from rapidfuzz import fuzz, process, utils


def closest_match(product_name: str) -> tuple:
    best_name, score, _ = process.extractOne(
        product_name,
        second_list.name,
        scorer=fuzz.token_set_ratio,
        processor=utils.default_process,  # lowercase and strip punctuation
    )
    return best_name, score


best_name, score = closest_match("Samsung Stereo Bluetooth Headset In Black - SBH500")
print(f"Closest match: {best_name}  (score {score:.1f})")
Every word in the second list’s name also appears in the first list’s name, so RapidFuzz gives it a perfect score and finds the right match.
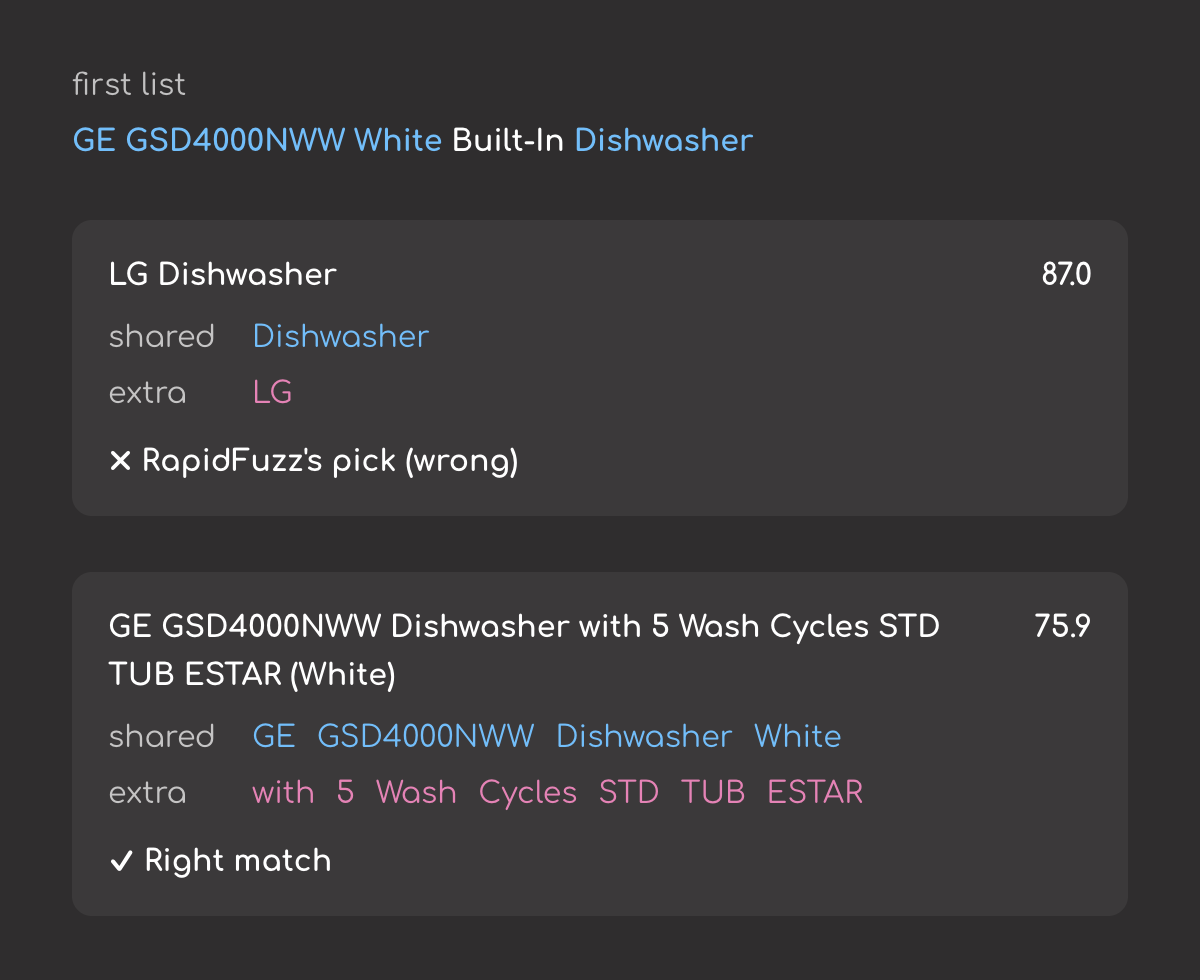
Now try a harder product, where the right match adds many extra words:
First list:    GE GSD4000NWW White Built-In Dishwasher - GSD4000WH
Right match:   GE GSD4000NWW Dishwasher with 5 Wash Cycles STD TUB ESTAR ( White) - gsd4000nww
They are the same product because both carry the model number GSD4000NWW.
product_name = "GE GSD4000NWW White Built-In Dishwasher - GSD4000WH"
right_match = "GE GSD4000NWW Dishwasher with 5 Wash Cycles STD TUB ESTAR ( White) - gsd4000nww"

best_name, best_score = closest_match(product_name)
right_score = fuzz.token_set_ratio(product_name, right_match, processor=utils.default_process)

print(f"Closest match: {best_name}  (score {best_score:.1f})")
print(f"Right match:   {right_match}  (score {right_score:.1f})")
The right match shares more words, but it also adds more extra words, so it scores lower.
Merging every product in the first list with its closest match gives these results:
| Merged | Correct | Wrong |
|---|---|---|
| 1,081 | 740 | 341 |
Nearly 1 in 3 merges is wrong.
Match Meaning with Sentence Transformers
Sentence Transformers turns text into a list of numbers, called an embedding, so texts with similar meaning end up with similar numbers. The similarity between two embeddings runs from 0 to 1.
numbers = similarity to "cell phone"

        ★ cell phone
          ● mobile phone (0.87)

              ● laptop (0.44)


                          ● banana (0.31)
Because Sentence Transformers compares meaning instead of letters, it might do better on the dishwasher example that RapidFuzz got wrong:
First list:    GE GSD4000NWW White Built-In Dishwasher - GSD4000WH
Right match:   GE GSD4000NWW Dishwasher with 5 Wash Cycles STD TUB ESTAR ( White) - gsd4000nww
Ask Sentence Transformers for the closest match:
from sentence_transformers import SentenceTransformer, util

model = SentenceTransformer("all-MiniLM-L6-v2")
second_list_vectors = model.encode([utils.default_process(name) for name in second_list.name])

query = model.encode(utils.default_process("GE GSD4000NWW White Built-In Dishwasher - GSD4000WH"))
best = util.semantic_search(query, second_list_vectors, top_k=1)[0][0]
print(f"Closest match: {second_list.name[best['corpus_id']]}  (similarity {best['score']:.2f})")
As expected, Sentence Transformers finds the right match. This is because it rewards shared details such as the brand, model number, and color. Here is how much each detail adds:
similarity to: GE GSD4000NWW White Built-In Dishwasher

Dishwasher                        0.65
+ GE                              0.75   +0.10   brand matches
+ GSD4000NWW                      0.91   +0.16   model number matches
+ White                           0.95   +0.04   color matches
Now let’s try a product where a wrong match shares more words than the right one. I expect Sentence Transformers to pick the wrong one:
First list:    Sony 400 Disc MegaStorage CD Changer - CDPCX455
Right match:   Sony CDP-CX455 CD Player/Changer - CDPCX455        <- same model number
Wrong match:   Sony CDP-CX355 300 Disc MegaStorage CD Changer     <- more words in common
Run Sentence Transformers and show its top 2 matches:
query = model.encode(utils.default_process("Sony 400 Disc MegaStorage CD Changer - CDPCX455"))
for hit in util.semantic_search(query, second_list_vectors, top_k=2)[0]:
    print(f"{hit['score']:.2f}  {second_list.name[hit['corpus_id']]}")
As I expected, Sentence Transformers picks the wrong match.
Merging every product in the first list with its closest match gives these results:
| Merged | Correct | Wrong |
|---|---|---|
| 1,081 | 763 | 318 |
Still nearly 1 in 3 merges is wrong, only slightly better than RapidFuzz.
Ask Jev Which Product Is the Same
TypeSafe Jev is a decision model. Instead of generating text, it answers a question with fixed answers and returns the probability of each one.
For example, here is the same question asked to a chat model and to Jev:
review:     "Cheaper than the store, though the left earbud crackles."
question:   What is this review about? (product quality, price, shipping)

Chat model (Claude Haiku 5.5):
  **Product quality.** The review's complaint is that the left earbud
  crackles. ...

Jev:
  product quality   0.79   <- picked
  price             0.21
  shipping          0.00
Unlike RapidFuzz and Sentence Transformers, Jev:
- Follows a rule you give it, so you can specify what “the same product” means in your data
- Answers with a probability, so you can match the pairs with high confidence and review the rest
- Runs fast and cheap, so checking thousands of pairs is practical
Start with the CD changer that Sentence Transformers got wrong:
First list:    Sony 400 Disc MegaStorage CD Changer - CDPCX455
Right match:   Sony CDP-CX455 CD Player/Changer - CDPCX455
Let’s give Jev the product and 3 similar names from the second list, plus “none of these”. We will also specify what makes two products the same: the same model number, capacity, and color.
from typesafe_sdk import Choice, TypeSafeClient

client = TypeSafeClient(model="jev-latest")


def ask_jev(product_name: str, shortlist: list) -> dict:
    response = client.system_one(
        state=product_name,
        questions={"match": Choice(
            instructions=(
                "Which candidate is the same product? Same model, same capacity or size, "
                "and same color or variant. Different model numbers mean different products."
            ),
            criteria={name: None for name in shortlist + ["none of these"]},
        )},
    )
    return response.choices["match"].probabilities


cd_changer = ask_jev(
    "Sony 400 Disc MegaStorage CD Changer - CDPCX455",
    [
        "Sony CDP-CX355 300 Disc MegaStorage CD Changer",
        "Sony CDP-CX455 CD Player/Changer - CDPCX455",
        "Sony CDP-CE375 CD Player/Changer - CDPCE375",
    ],
)
for name, probability in cd_changer.items():
    print(f"{probability:.2f}  {name}")
Jev gives the right match the highest probability, 0.93. This means it follows the rule we gave it: different model numbers mean different products.
Let’s compare this result with the scores from the other two tools:
| Candidate | RapidFuzz | Sentence Transformers | Jev |
|---|---|---|---|
| Sony CDP-CX455 CD Player/Changer (right match) | 73.8 | 0.86 | 0.93 |
| Sony CDP-CX355 300 Disc MegaStorage CD Changer | 94.5 | 0.93 | 0.00 |
| Sony CDP-CE375 CD Player/Changer | 62.8 | 0.83 | 0.00 |
Only Jev ranks the right match first. It is also confident the other two are wrong.
What does Jev do when none of the choices is the right match? Let’s find out by giving it three wrong candidates:
First list:    Sony Stereo Audio Receiver - STRDE197

Candidates:    Sony STR-DG720 A/V Receiver - STRDG720    <- not a match
               Sony STR-DG920 A/V Receiver - STRDG920    <- not a match
               Sony STR-DG820 A/V Receiver - STRDG820    <- not a match
receiver = ask_jev(
    "Sony Stereo Audio Receiver - STRDE197",
    [
        "Sony STR-DG720 A/V Receiver - STRDG720",
        "Sony STR-DG920 A/V Receiver - STRDG920",
        "Sony STR-DG820 A/V Receiver - STRDG820",
    ],
)
for name, probability in receiver.items():
    print(f"{probability:.2f}  {name}")
Jev picks “none of these”, which is the right answer. RapidFuzz and Sentence Transformers always return a closest name, so they would merge a wrong one.
Combine Sentence Transformers and Jev
We can’t give Jev all 1,092 names from the second list as answers, because a Choice question takes at most 255. So let’s use Sentence Transformers to keep the 3 closest names for each product, and Jev chooses among them.
1,092 names in the second list
              │  Sentence Transformers
              ▼
3 closest names
              │  Jev
              ▼
1 match, or none
Because Jev returns a probability, each product can be merged, left unmatched, or sent to a person to review.
Top answer "none of these"?  ── yes ──▶  leave unmatched
          │ no
          ▼
Probability above 0.7?       ── yes ──▶  merge
          │ no
          ▼
Probability below 0.3?       ── yes ──▶  leave unmatched
          │ no
          ▼
send to a person
Running this on every product in the first list gives these results:
| Route | Pairs | Correct | Wrong |
|---|---|---|---|
| Merge (p > 0.7) | 808 | 807 | 1 |
| Send to a person | 62 | ||
| Leave unmatched | 211 |
Jev merges 808 pairs with only one wrong. The run took about 35 seconds and cost about $0.03 for 1,081 questions. With one wrong merge out of 808, the merges are reliable enough to apply automatically.
Which Approach Should You Use?
Here are the three approaches side by side:
| Approach | Merged | Correct | Wrong merges |
|---|---|---|---|
| RapidFuzz | 1,081 | 740 | 341 |
| Sentence Transformers | 1,081 | 763 | 318 |
| Top 3 + Jev (p > 0.7) | 808 | 807 | 1 |
RapidFuzz and Sentence Transformers are free, but about 1 in 3 of their merges is wrong, so you still have to check every one of them. Jev costs about $0.03 for the whole list and makes only one wrong merge, so you only need to look at the few products it is unsure about. This means you end up saving a lot by spending a little.
So should you always use Jev? No. I recommend starting with the free tools to see how well they work for your data, and moving to more complicated tools only if the current ones are not good enough.
As a rule of thumb:
- Use RapidFuzz when names look almost the same but differ in typos, case, punctuation, or word order.
- Use Sentence Transformers when names use different words for the same product, and no near-identical products are in the list.
- Use Jev when you need rules to decide if two products are the same, such as matching the model number, capacity, or color.
Stay Current with CodeCut
Easy-to-digest articles on Python, AI, and open-source tools. Delivered twice a week.
Related Tutorials
- Structured Output Tools for LLMs Compared: Get fixed, typed answers from a chat model
- Auto-Optimize an LLM Classifier with DSPy: Build a classifier from prompts and let DSPy tune them
- langextract vs spaCy: AI-powered against rule-based extraction of entities from text